/greg(ular)?expressions/

19 years in tech, most recent 11 as a Product Manager at start-ups and scale-ups. I like to work collaboratively on ambiguous problems. My approach simplified is “Find what’s valuable and do it”. On the side I like to mess around with stuff.

Open toFounding / Lead PM

BasedLondon, UK

ContactEmail / LinkedIn

THINGS I’VE BEEN PLAYING WITH LATELY
01 / iPhone app3 live sites

Snagster

3Live sites

I observed a professional Interior Designer (whom I live with) produce a “snagging” document of defects for a contractor to resolve on a real world construction site. The workflow was so painful I felt compelled to do something about it.

Hundreds of photos taken on-site gone through one by one to re-identify what was wrong, describe, and group. Effectively re-snagging the whole site a second time to distil into a spreadsheet.

Existing apps were add-ons for bigger project management systems or poor quality, so I built one. Optimised for capture while walking the site. Including Excel report generator with every location, photo, description and floor-plan pin already in it. It’s been used across multiple visits on three live construction sites, and I’m (slowly) working on getting it submitted to the App Store.
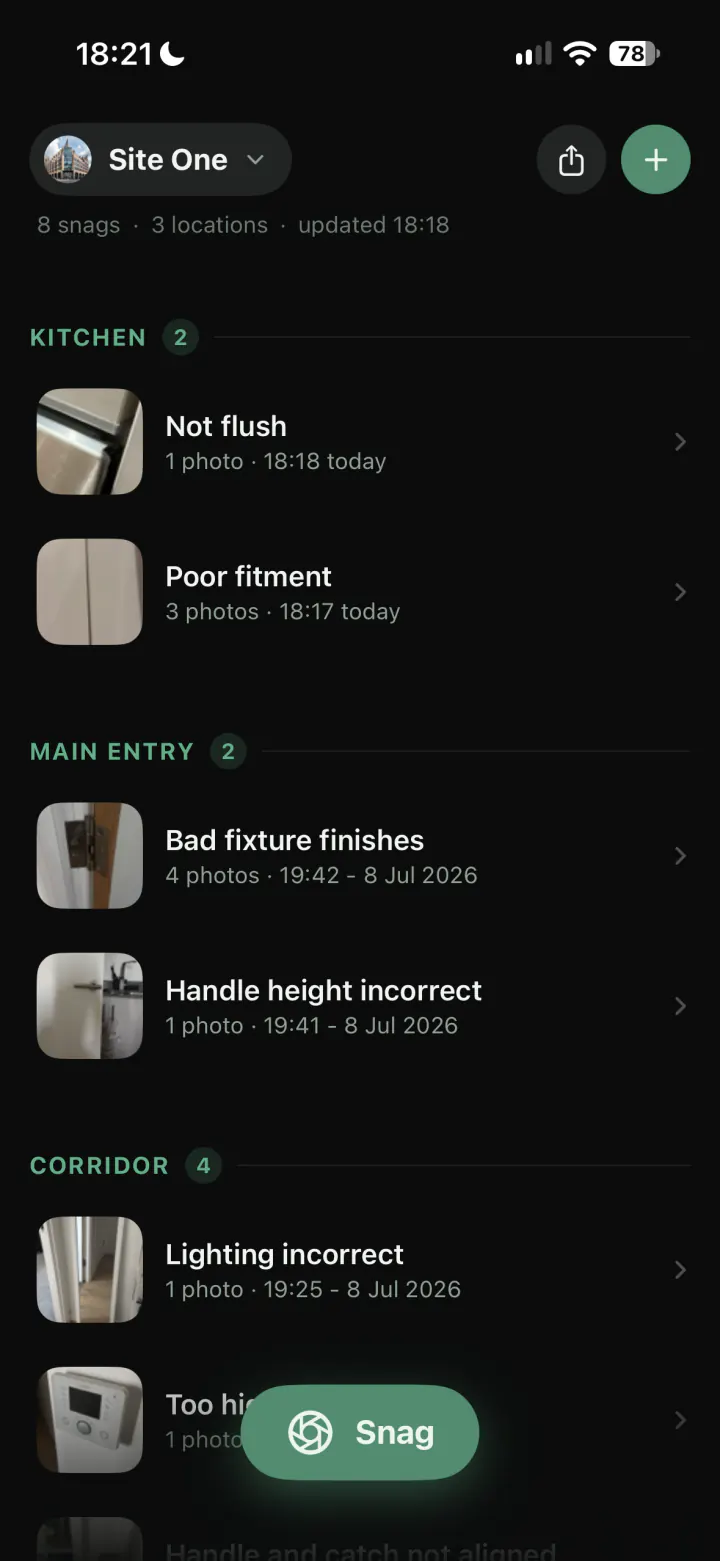
Snagster site view: snags grouped by location, each with a thumbnail, photo count and timestamp, with a Snag button to open the camera
01 / Snag List
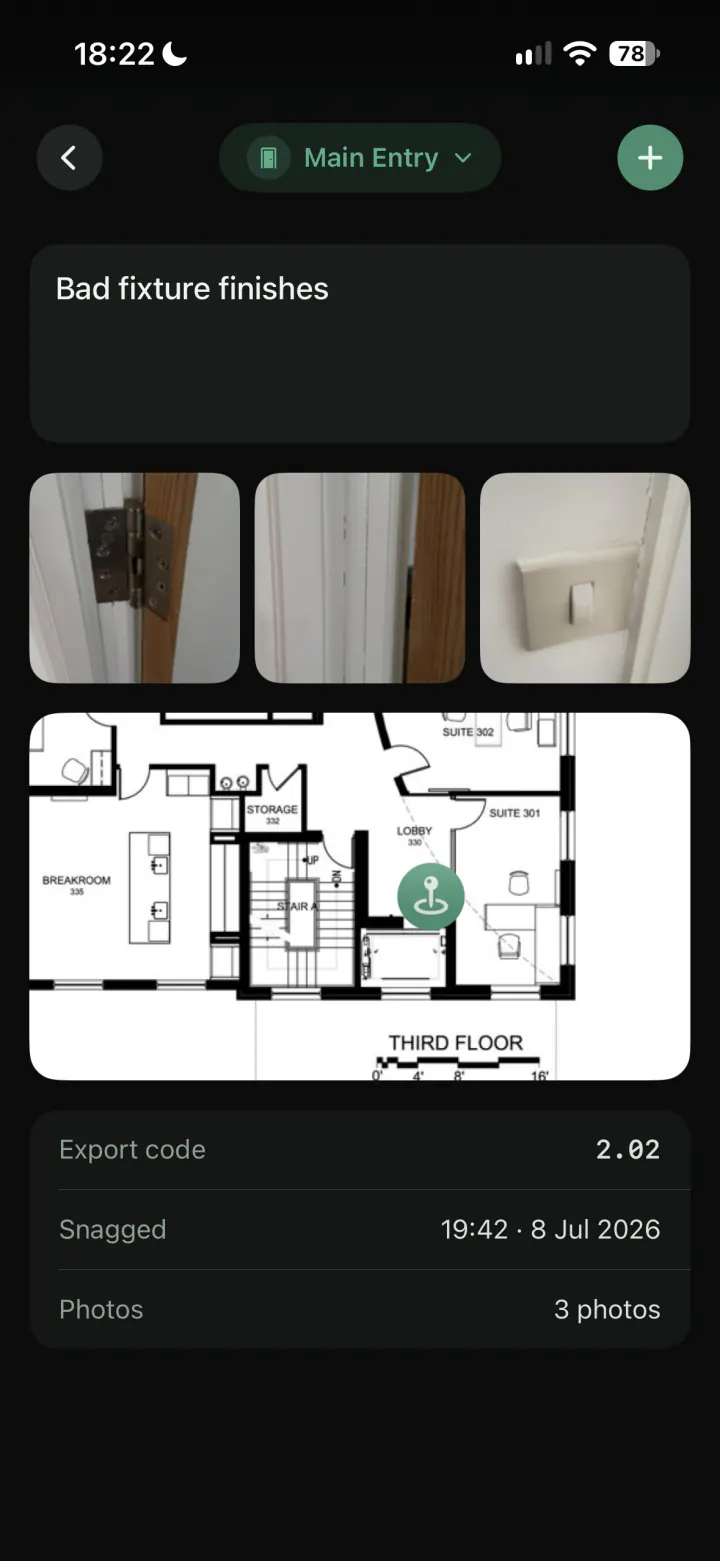
Snagster snag detail: a written description, a grid of annotated photos, and a floor plan with the snag’s pin
02 / Snag detail
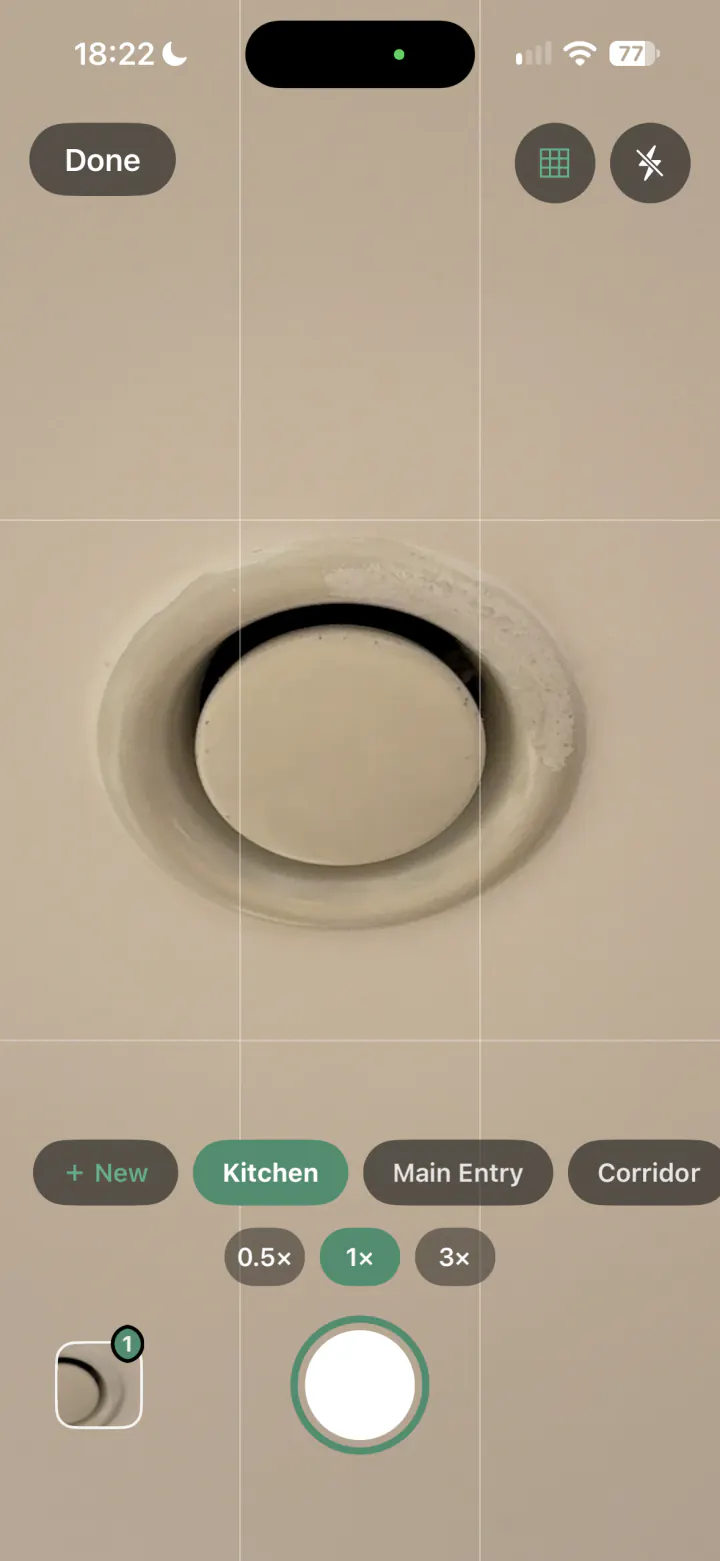
Snagster camera: grid overlay, flash toggle, 0.5x, 1x and 3x zoom presets, and a shutter button
03 / Camera
Before
  1. 1Capture all defects from multiple angles into camera roll
  2. 2Jot a note in a paper notebook, or just try to remember
  3. 3Back at the desk, reconcile it all in Excel by hand
After
  1. 1In the camera shoot snag after snag, grouped by location
  2. 2Add descriptions and floor-plan pins for each grouped snag
  3. 3Export an Excel with everything embedded
  1. 01

    v0.0 wasn’t an app. It was inserting photos inline to Apple Notes and writing a line below. Even one long list to copy from into the spreadsheet was a big improvement. I was confident the copy & paste stage could be eliminated.

  2. 02

    v1.0 was too rigid. A hierarchical data flow and an inflexible sequence. Type a location, write a description, add photos, then save. It kept the data clean and flow obvious, but it fought you if you wanted to shoot first. The test user took every photo with the native camera and filled the app in on the way home.

  3. 03

    v2.0 is camera first. Site visits are rare, rushed, and chaotic. You cannot easily take more photos later, they are the priority. I didn’t want there to be a “wrong” flow: a snag can start from a burst of photos or from a sentence. New Snag defaults to camera.

  4. 04

    A camera that keeps up. I had to optimise significantly to allow for rapid sequential capture, swinging from angle to angle. That meant tuning shutter behaviour, image scale, and compression. Offloading any processing to avoid impeding the next shot.

Hours reduced to minutes with better tooling and the wider workflow left unchanged.

TypeiPhone app / iOS 26

Built withClaude Code / OpenCode / SwiftUI / SwiftData / AVFoundation

Field zone3 live construction sites
02 / Local RAG pipeline13 years indexed

Journal, LLM’d

13Years indexed

I’ve kept a journal for thirteen years, and I wanted to talk to it. Queries like; How has my mood shifted over time? What was I doing five years ago today? Show me every photo with a squirrel in it. However, it being deeply personal I didn’t want it leaving my machine.

I built a local pipeline. Entries are chunked and vectorised. A local model describes every photo in words, each entry gets a sentiment score, and everything is indexed so any AI assistant can search it in about 50 ms. Nothing is uploaded anywhere.

  1. 01

    Context vs Search. Initially I just pointed a local model at an export and I learned how inefficient large context windows are. I next chunked and vectored the journal entries too aggressively, leaving the agent with only snippets and a lack of overall context. I needed to provide bigger chunks but also more flexible search options in the query API.

  2. 02

    Teaching the AI to use it. This took longest. The server worked but the agent would often pick sub-optimal queries and endpoints to answer my questions. Extending the API docs with example use cases for each endpoint and which to combine for each type of question significantly dropped the error rate.

  3. 03

    Photos. Image descriptions went inline with the entry text at first, which skewed the sentiment scores. Once I noticed I wrapped them in tags during interpretation so they can be selectively included.

Usually wrong to almost always correct. The infra was the relatively easy bit. Teaching the agent(s) to use it was the job. Model, Harness, Instructions.

TypeLocal RAG pipeline

Built withPython / MLX / Gemma 3 / RoBERTa / LanceDB / FastAPI

Query time~50 ms warm

03 / Noise complaint1,352 horns logged

The loud junction

1,352Horns logged

A junction below my flat in London was rebuilt this year, drivers honk at it around 53 times a day. I had to try something.

I treated it like a product problem: find the root cause, gather compelling evidence, and lobby those who can actually fix it with what they care about.

Horns per hour31 days
  1. 01

    Finding the cause. Impatient drivers honking are a symptom (of many things). In this case the most common trigger was lead cars not moving on green. Seems something about the timing is suboptimal.

  2. 02

    Not fooling myself. I knew “cars are loud” wasn’t a winning approach and I was confident the number of horns was significant enough to cross reasonable thresholds, so I decided to log how many I heard and when I heard them.

  3. 03

    The low-tech logger won. I tried automating it first: Python triggered on frequencies, microphones near the windows. It wasn’t reliable enough. I went simpler, an Apple shortcut wired to my phone’s action button that writes a log line with the date and time. Hear a horn, press the button.

CLAUDE

  1. >>>

    The Options. Working out which kind of complaint goes to whom looked like the most painful. Claude had several options, that made the logging feel worth doing because I knew I would have a path forward.

  2. >>>

    Analysis. Reviewed photos of the junction for design problems, and found patterns in my log, like the school run peaks and the salvos.

  3. >>>

    The write-up. Drafted most of what went to the councillor in the pack, including annotated frames pulled from my videos showing drivers not moving.

“We’re definitely the right people to raise this with. I’m sorry you’re having this issue and I totally understand how it could impact your quality of life.”
A ward councillor, replying to the pack
TimelineStatus: active
  1. 1,352 horns logged by hand in a month
  2. Video of the trigger, plus a two-page evidence pack
  3. Sent to my ward councillors with three asks
  4. A councillor on the transport scrutiny committee lodged a formal enquiry
  5. Waiting on the council’s response You are here
  6. Next: highways complaint, signals review, road safety audit request

So far: 1,352 horns, a two-page pack, and a councillor chasing it. I made it easy for them to understand and get on-board.

TypeEvidence + advocacy

Built withPython / Claude / an iPhone action button

StatusActive, awaiting the council

04 / Agent context

Knowledge base

An agent is often only as good as the context you give it, and that context is painful to rebuild. My solution is bespoke wikis that agents build and maintain themselves, so each session starts from everything the last one learned. It’s my take on Karpathy’s “LLM Wiki” pattern and it’s just markdown files in a folder. No app, no database, fully agnostic.

The goal is context I can trust. Every claim links to its source, and anything the agent worked out for itself has to say so. Raw local sources sit in a folder that’s never edited, so the whole wiki can be audited by citation.

I use it for any topic with enough complexity, one wiki per topic; market research for a new idea, company research before an interview, etc.

kb/Markdown only

kb/

├── raw/ # sources · never modified

└── wiki/ # agent-written · [[links]]

├── index.md # the single entry point

└── log.md # every change · append-only

Citations

claim … (source: raw/annual-report.pdf)

reasoning … (source: inferred) + why it holds

Graph viewEvery link, as A REAL wiki grew

Context you can trust is the thing that compounds. What evidence is there to support X? What gaps in knowledge do we have? Lint the wiki.

TypeAgent context / research workflow

Built withClaude Code / Markdown / Obsidian

RuleEvery claim cites a source

05 / Offline TTS pipeline20 episodes

Podcast generator

20Episodes

I walk for about an hour most days, and I wanted to use that time to build a baseline on whatever I was researching: a company, a market, a topic. Ideally based on one of my Knowledge Bases. I tried Google’s NotebookLM first but it wasn’t flexible enough. So this turns any correctly formatted script into a two-host audio briefing. An LLM drafts the script; my Mac voices it offline, with two cloned voices and pauses that sound roughly human, then masters it to podcast loudness. All local.

Sample episodeRendered by this pipeline
0:00 / 0:28 Alex & Jordan
Transcript

Jordan: You’re listening to two voices that don’t exist.

Alex: Cloned from short reference clips. Rendered on a laptop, offline.

Jordan: No cloud, no API bill.

Alex: A language model writes the script. So why don’t we drift?

Jordan: The first batch is thrown away. Its last ten seconds join the reference, so the pace holds.

Alex: Pauses vary too.

Jordan: Shorter after a question. Longer at a section break.

Alex: The script mattered more than the code.

Jordan: More than the cloning?

Alex: More. Flat tone, numbers spelled out, about 180 words a minute.

Jordan: Which is roughly what you’ve just heard.

The first version worked, but it was robotic and slow. Getting it to sound human meant iterating on three things: the voices, the speaking pace, and the pauses.

  1. 01

    Same two people, start to finish. Each voice is cloned from a short reference clip, and wants to drift over a long episode. I generate the first few turns, throw it away, and bolt its last ten seconds onto the reference. This prevents the drift and keeps the hosts sounding consistent.

  2. 02

    Pauses that sound like conversation. Shorter after a question or before a quick reply, longer at section breaks. A few ifs in gap(), works well enough.

  3. 03

    The script matters more than the code. A one-page writing guide for the LLM does more for how natural it sounds than anything in the pipeline. Use a flat tone, no exclamation marks, numbers spelled out, about 180 words a minute.

20 episodes, no API bill, and an hour a day turned optionally into prep time. All inside a closed system I can tweak and control.

TypeOffline TTS pipeline

Built withPython / MLX-Audio / Qwen3-TTS / FFmpeg

Mastered to-16 LUFS

06 / Parser + web page531 albums parsed

Unwrapped

531Albums parsed

It started as a time capsule: I wanted to get the music library off my partner’s old iPod for posterity. Then, mostly as a joke, I decided it deserved a Wrapped. All it has to go on is iTunesDB, an undocumented binary database that was never meant to be read by anything except iTunes. A stdlib-only Python parser turns it into JSON, and a tap-through, Wrapped-style page turns that into something you’d actually look at: 255 artists, 531 albums and 56 years of music on one clickwheel.

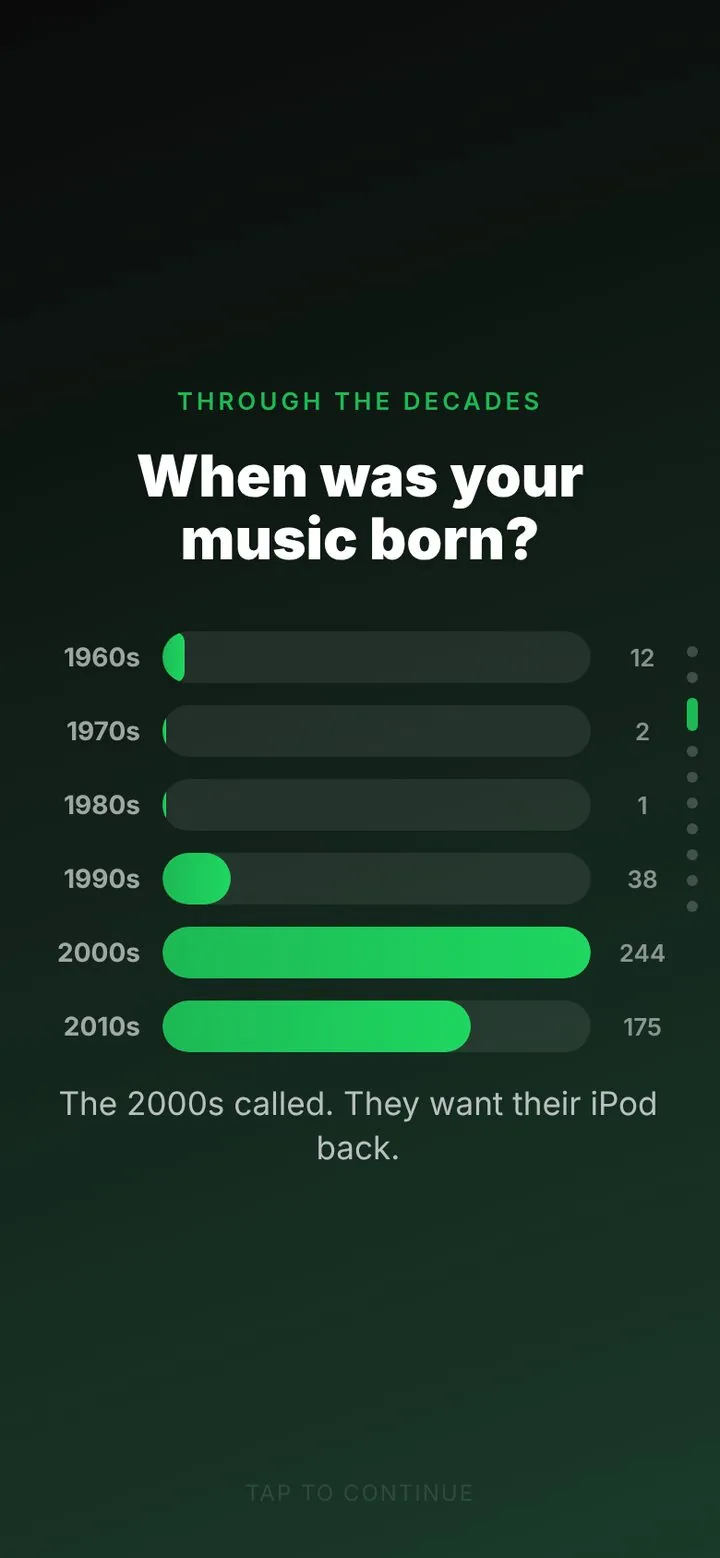
Unwrapped card: albums by decade, peaking in the 2000s with 244
01 / Albums by decade
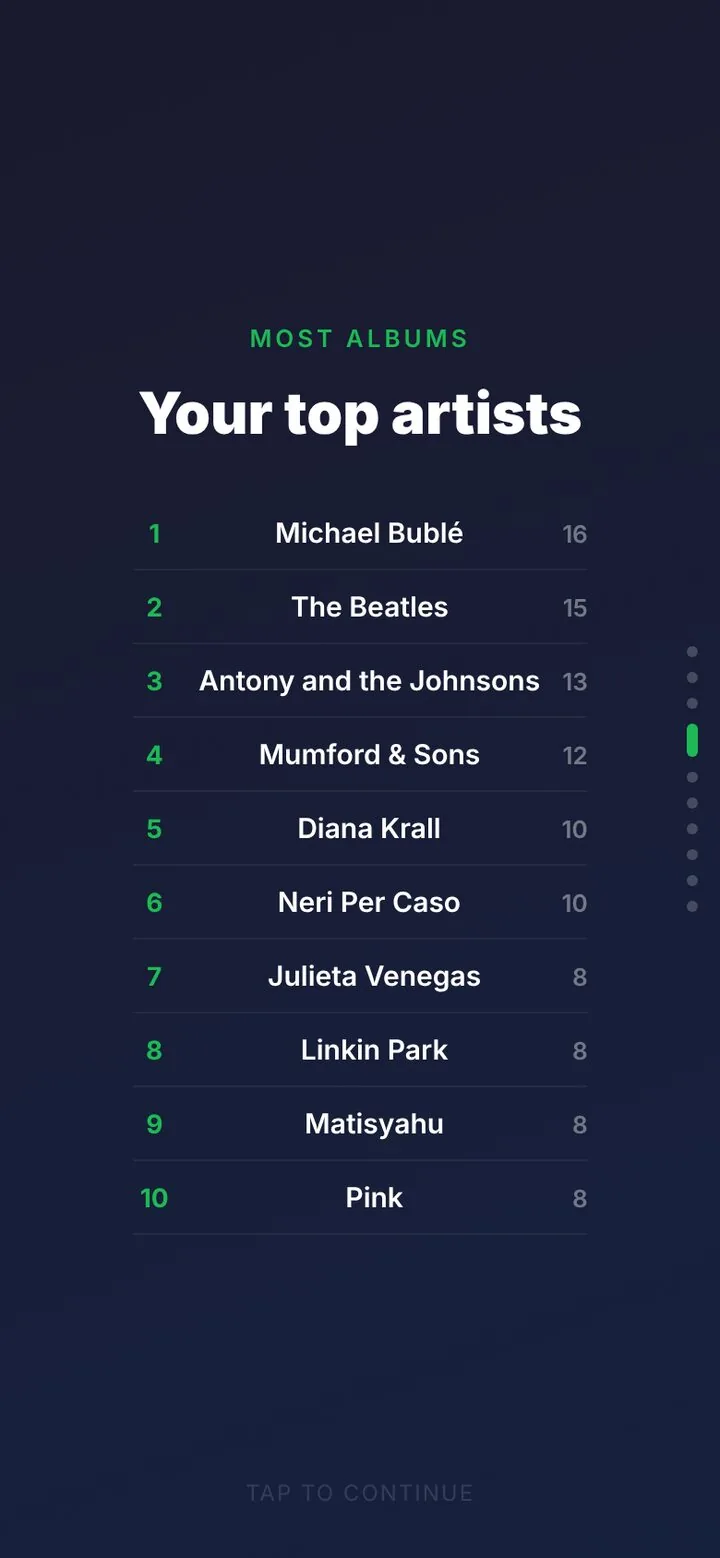
Unwrapped card: top ten artists by album count, led by Michael Bublé and The Beatles
02 / Top artists
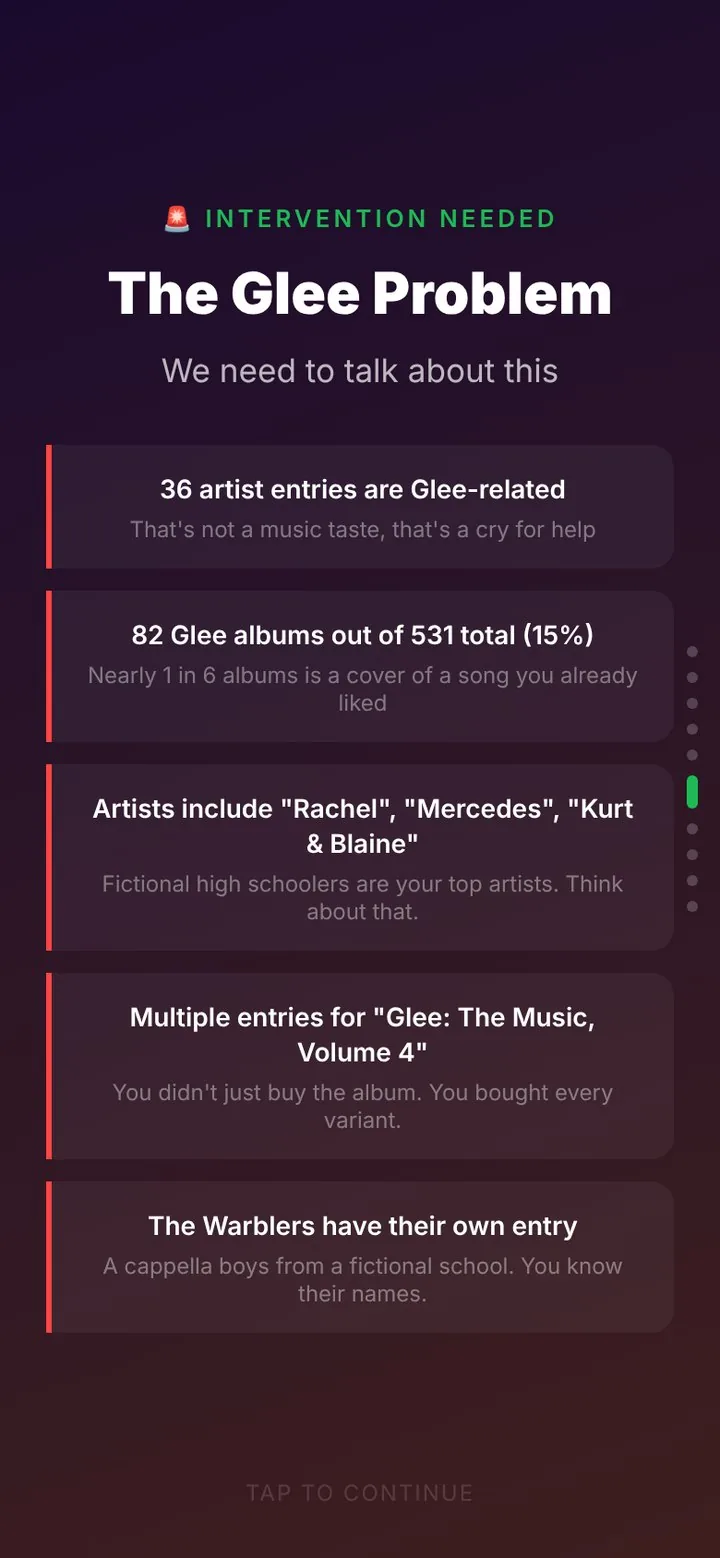
Unwrapped card: The Glee Problem, listing how many Glee albums and artist entries are on the iPod
03 / The Glee problem
  1. 01

    The data was a mess. Years of imports and stream rips: “Diana Krall” and “Diana krall” as two artists, “Florence + The Machine” and “Florence and the Machine”.

  2. 02

    Lookup tables, not a model. A normalisation map merges the duplicates, keyword matching catches the Glee cast filed under character names, and genres come from hand-picked artist lists. For 255 artists, that’s quicker than wiring up anything clever.

  3. 03

    One file, opens anywhere. The required data is inlined in the HTML: no server, no build step, no dependencies.

CLAUDE

  1. >>>

    The parser. I tried open-source Python libraries and scripts first, but none of them could decode the library. I tried Claude on a whim, and it got the parser working.

  2. >>>

    The page. Claude built it. I picked which stats were worth showing and told it exactly what to mock.

531 albums, 255 artists, cleaned up with hand-written lists. I didn’t need it to ever scale.

TypeParser + web page

Built withPython / vanilla JS / Claude / 5th Gen iPod

DependenciesZero

07 / Firefox extension30 minutes to build

Reddit filter

30Minutes to build

I like seeing cute animals on the internet, but subreddits kept bumming me out: sick squirrels, dead hamsters, cats being put down. I didn’t need to see that, I was there for cute. Simple solution; a few regexes applied as the page renders do the job instantly, privately, and for free. In the past I probably wouldn’t have bothered, but it took me less than 30 minutes with Claude Code.

content.jsAbridged

// title-only keyword match. no network, no model, no latency.

// upgrade path: scan body/flair, or an LLM classifier.

const ANIMAL = /\b(dogs?|cats?|kitt(en|y)|birds?|pon(y|ies)|…)\b/i;

const DEATH = /\b(died|put (\w+ ){0,3}down|rainbow bridge|…)\b/i;

const INJURY = /\b(injured|mauled|emergency vet|…)\b/i;

function shouldHide(post) {

const title = titleOf(post);

// "TuxedoCats" → "Tuxedo Cats" so \b can match

const aboutAnimal = ANIMAL.test(title) || isAnimalSub(subOf(post));

return aboutAnimal && (DEATH.test(title) || INJURY.test(title));

}

// infinite scroll: batch DOM mutations into one scan per frame

new MutationObserver(() => requestAnimationFrame(scan))

.observe(document.body, { childList: true, subtree: true });

  1. 01

    Dead wasn’t enough. The first version only hid dead animals. Injuries came next, so a post now hides when it’s about an animal and mentions either.

  2. 02

    The bug report. “I lost my baby” in r/TuxedoCats got through. No animal word in the title, and only the title was checked. The fix was to treat the subreddit as context too, splitting “TuxedoCats” into “Tuxedo Cats” so “cat” could match.

  3. 03

    The review. I asked Claude to review the code after that fix. It found eleven more problems, and they cut both ways. All eleven got fixed.

Getting it signed by Mozilla was for a lazier reason: unsigned extensions have to be re-added in dev mode every time Firefox restarts. Ain’t nobody got time for that.

Thirty minutes and a code review later reality improved.

TypeFirefox extension, signed by Mozilla

Built withJavaScript / WebExtensions

Network callsNone